TRUSTED DATA REFINERY
AI-Ready Data
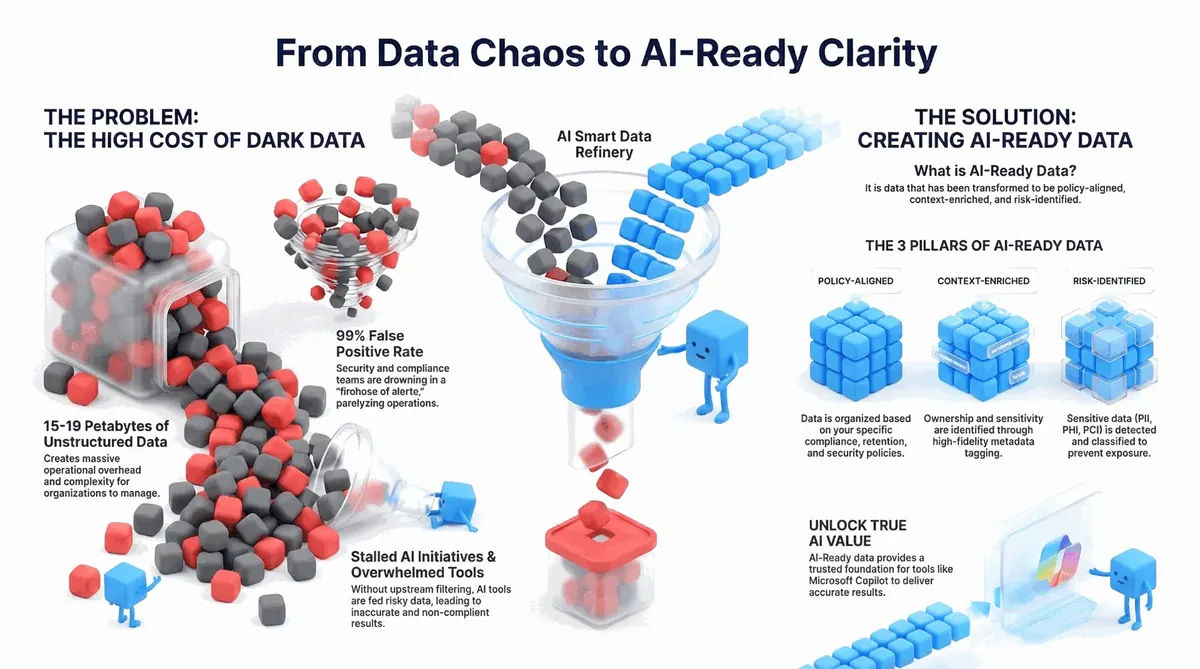
Transform Untrusted Data into AI-Ready Trusted Data @ Speed and Scale, curated, defensible, policy-aligned information for an authorized use case and subsequent evaluation.
The Foundation. Three Pillars of AI-Ready Data.
Governance Ready
Policy-Aligned
Data organized through Smart Stack based on policy, compliance, utilization, and security requirements.
Metadata Enhanced
Context-Enriched
Ownership, sensitivity, and ROT status identified through Data Identifier with high-fidelity metadata tagging.
Compliance Protected
Risk Identified
PII, PHI, PCI, and regulated content detected and classified before any AI utilization.
Understanding AI-Ready Data
What is Untrusted Data
Every enterprise accumulates Untrusted Data, information that exists inside the organization but cannot be confidently used for analytics, compliance, or AI. Untrusted Data is the combination of Dark Data and Dirty Data.
Dark Data is unmanaged, unclassified, and often invisible content buried in file shares, SharePoint sprawl, legacy archives, email stores, and abandoned repositories. Dirty Data is inaccurate, duplicated, outdated, inconsistent, or misaligned data that degrades reporting, increases legal exposure, and undermines AI reliability.
Individually, these conditions create operational friction. Together, they create strategic risk. AI systems do not correct Untrusted Data, they amplify it.
From Untrusted Data to AI-Ready Trusted Data
Trusted Data Refinery exists to reverse data entropy. It transforms Untrusted Data into AI-Ready Trusted Data by identifying and eliminating redundancy, enriching and normalizing metadata, supporting policy review and governed retention decisions, structuring unorganized content, and reducing risk before AI ingestion. The result is curated, defensible, policy-aligned information for an authorized use case and subsequent evaluation.
The Transformation Process
Trusted Data Refinery acts as the "upstream refinery" for an organization's Unstructured Data estate. Its three components work together:
Data Reader inventories supported file estates in place. Coverage and throughput depend on source conditions, scan depth, and the validated deployment.
Data Identifier transforms Dark Data into Actionable Trusted Data by populating the Elasticsearch Indexing Database.
Trusted Data Collections contain selected information and retain source context for review before a supported AI integration.
Key Benefits
- Copilot Ready: Data prepared specifically for Microsoft Copilot consumption.
- Governance Review: Review selected information against policy and access requirements.
- Context Rich: Available metadata supports source traceability and evaluation.
- Risk Controlled: Investigate sensitive-data findings before an approved AI use case.
Conclusion
AI creates value from trusted inputs. Trusted Data Refinery is the engine that makes enterprise data trusted, and truly AI-ready. The result is AI-Ready Trusted Data @ Speed and Scale that your organization's AI systems can safely and effectively use.
Make Your Data AI-Ready
Transform your Untrusted Data into the AI-Ready Trusted Data foundation your enterprise needs.
Explore Trusted Data Refinery